Skip to content
ZJ

Artificial intelligence

The most interesting material I've ever built with.

I've been shipping AI products since large models became real — not demos, but systems in production: copilots that whisper in live meetings, agents that finish real workflows, retrieval that cites its sources, voices that hold a phone conversation and video models under genuine creative control.

  • 06 AI builds
  • Agents · RAG · Voice · Diffusion · Copilots
  • Local and cloud models
  • Evals, guardrails and human-in-the-loop by default

AI work

Shipped intelligence, not slideware.

Every build here runs — agents with enforced policies, retrieval with citations, voices with latency budgets, video with creative control.

Private beta

LiveCue AI

AI · Desktop · Real-Time Assistance

An AI meeting assistant that provides contextual live guidance while respecting presentation and screen-sharing workflows.

Challenge
Give speakers useful AI guidance during live meetings — transcribing, understanding context and suggesting responses — without ever leaking the assistant into a shared screen or recording.
Contribution
Built the desktop application: live transcription pipeline, contextual AI response generation across local and cloud models, meeting-platform integration and the privacy-aware overlay system.
  • Desktop app
  • Live transcription
  • LLM integration
  • Local models
  • Overlay rendering
  • Meeting platforms
View case study
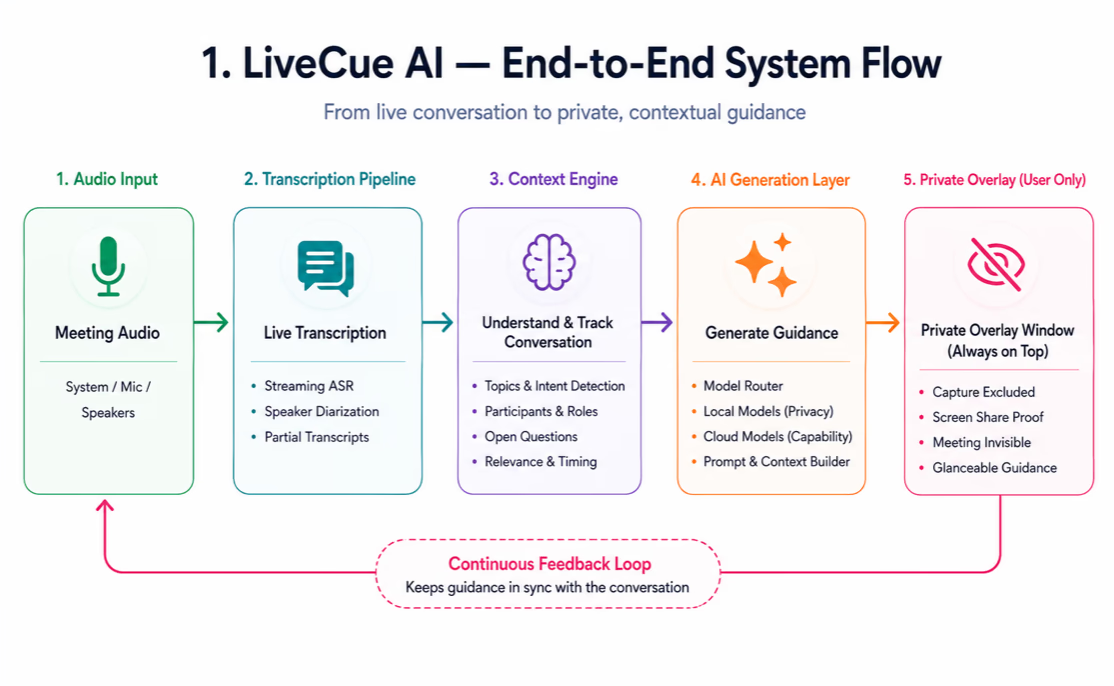
LiveCue AI end-to-end system flow: audio input, transcription pipeline, context engine, AI generation layer and a private user-only overlay, closed by a continuous feedback loop.
Concept · in development

Phandor

AI Automation · Productivity

An intelligent desktop automation concept designed to help users complete repetitive digital workflows.

Challenge
Let an AI agent operate a user's desktop to finish repetitive workflows — while keeping the human decisively in control of anything consequential.
Contribution
Designed the agent architecture: context understanding, workflow execution engine, human-approval checkpoints and the safety boundaries that decide what the agent may never do alone.
  • AI agents
  • Desktop automation
  • Workflow engines
  • Context models
  • Approval systems
View case study
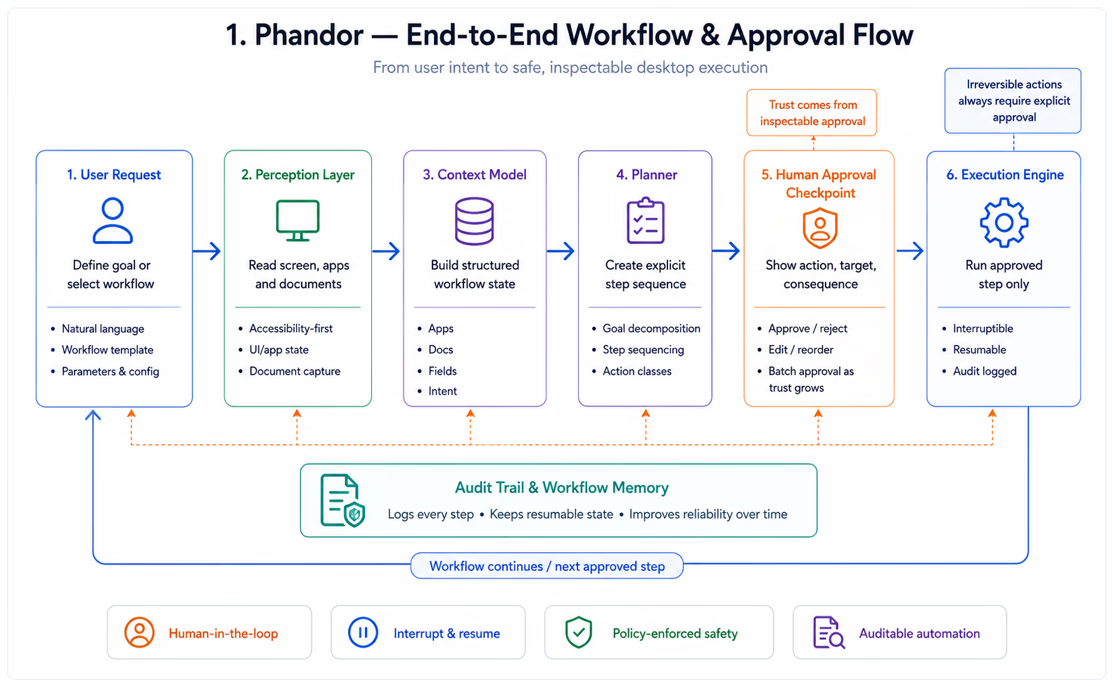
Phandor end-to-end workflow flow: a user request moves through the perception layer, context model and planner to a human approval checkpoint before the execution engine runs the approved step, with every stage writing to an audit trail.
Private build

AI Video Studio

AI · Generative Video · Platform Build

A Higgsfield-style generative video platform turning prompts and stills into cinematic, motion-controlled clips.

Challenge
Serve GPU-heavy diffusion video generation to consumers at tolerable latency and unit cost — while giving them real creative control over camera motion instead of a prompt lottery.
Contribution
Built the platform end to end: Next.js creation studio, Python inference services, GPU worker orchestration with queueing and progress streaming, motion-preset system, moderation pipeline and credits billing.
  • Next.js
  • TypeScript
  • Python
  • FastAPI
  • Diffusion models
  • GPU workers
View case study
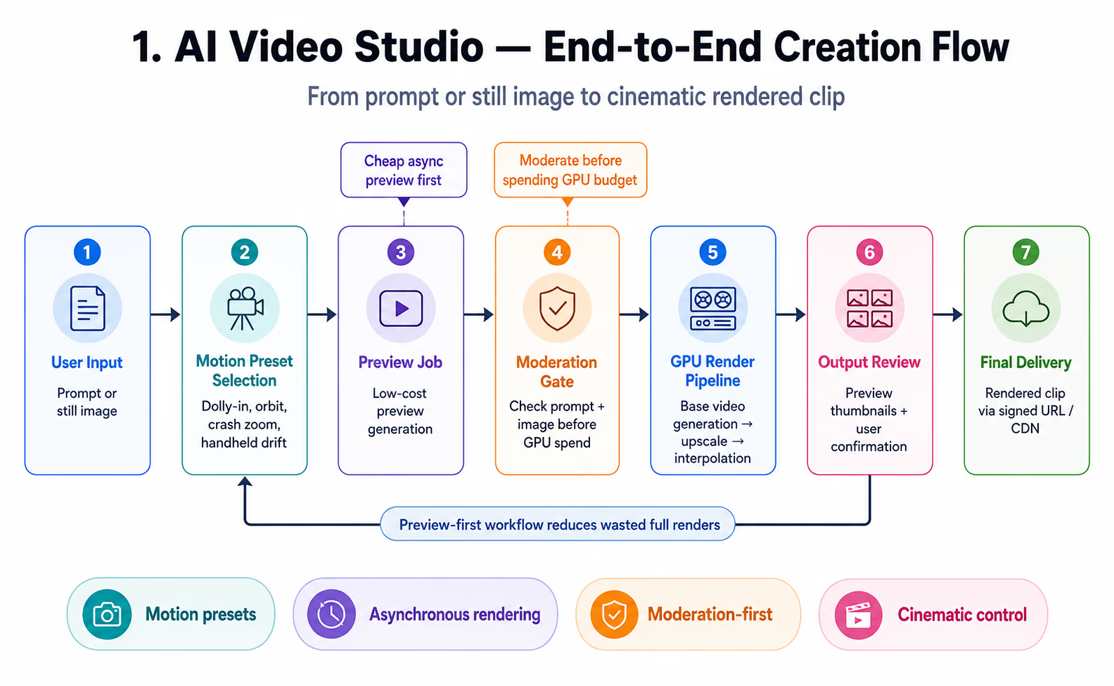
AI Video Studio end-to-end creation flow: user input and motion preset selection lead to a low-cost preview job, a moderation gate before GPU spend, the GPU render pipeline, output review and final delivery over CDN.
Delivered

Knowledge Copilot

AI · RAG · Enterprise Knowledge

A retrieval-augmented assistant that answers from an organization's own documents — with citations, not confidence tricks.

Challenge
Company knowledge lives in thousands of documents nobody re-reads. The copilot had to answer from that corpus accurately, cite its sources, respect who is allowed to see what — and refuse when it doesn't actually know.
Contribution
Built the full RAG system: ingestion and chunking pipeline, hybrid retrieval with reranking, permission-aware search, grounded generation with citations, and the evaluation harness that keeps quality honest.
  • TypeScript
  • Python
  • LLM APIs
  • Embeddings
  • pgvector
  • Hybrid search
View case study
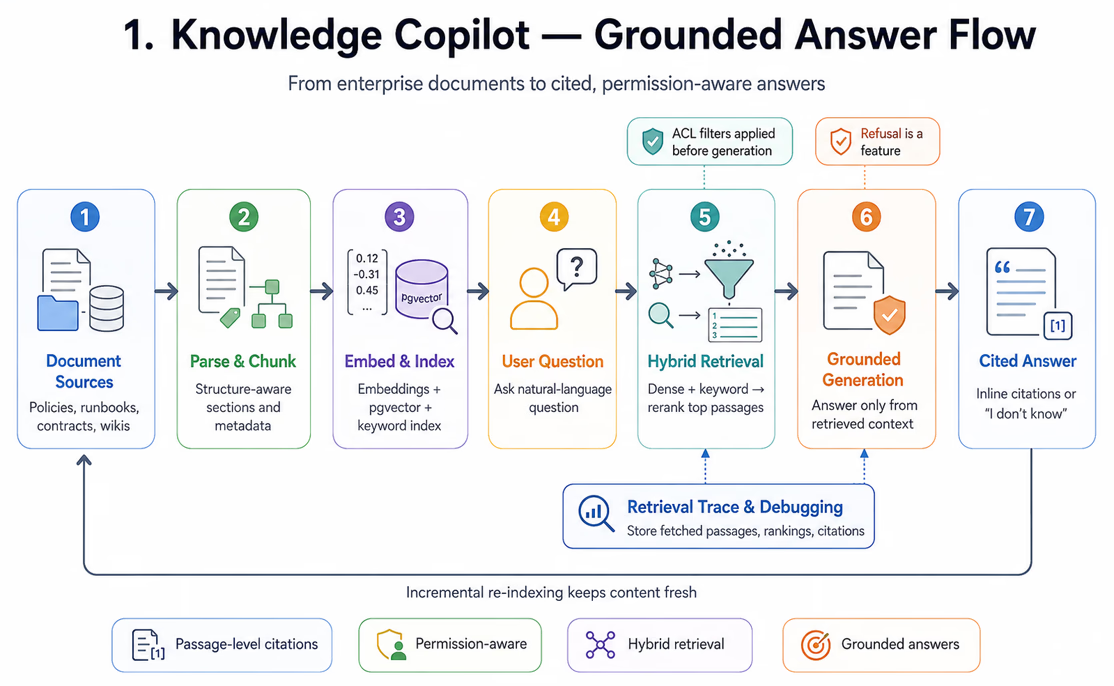
Knowledge Copilot grounded answer flow: document sources are parsed, chunked, embedded and indexed, then a user question runs through hybrid retrieval with ACL filters applied before grounded generation returns a cited answer or says it does not know.
Private beta

Autonomous Support Agent

AI · Agents · Customer Automation

A tool-using support agent that resolves real tickets end to end — and knows exactly when to hand off to a human.

Challenge
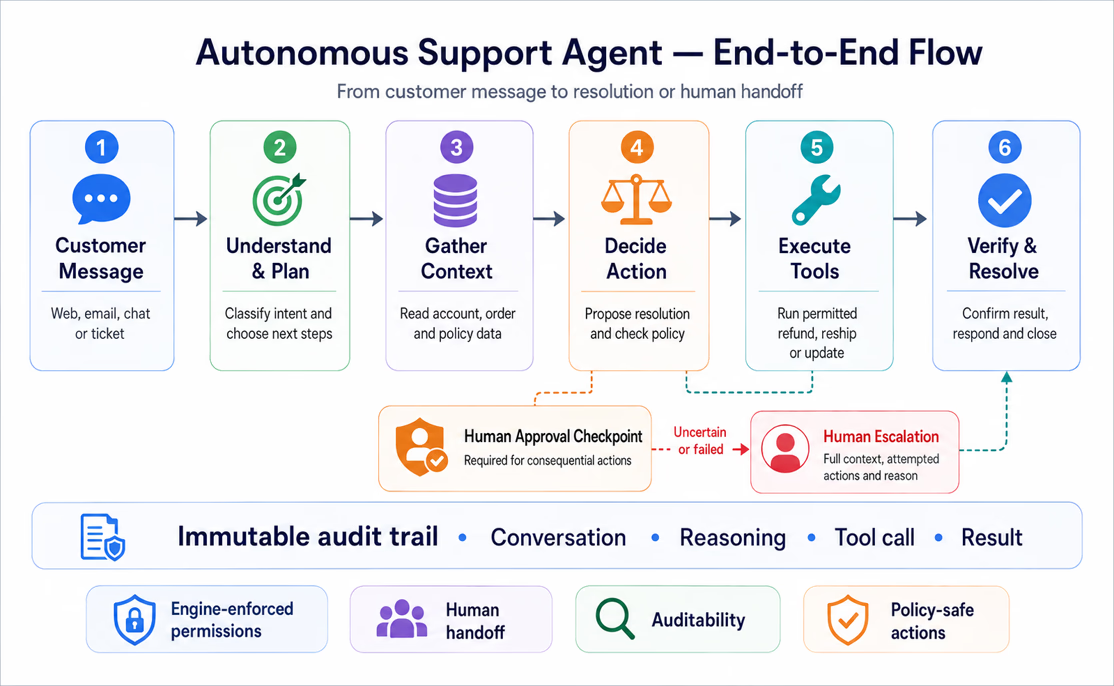
Support automation usually means deflection. The goal here was resolution: an agent that can look up orders, apply policies and execute real actions — with mechanical limits on what it may do without a human.
Contribution
Designed and built the agent system: the reasoning loop, typed tool layer, policy engine gating consequential actions, escalation logic, and the simulation-based evaluation rig that replayed historical tickets before anything touched production.
  • TypeScript
  • Node.js
  • LLM tool use
  • Function calling
  • RAG
  • PostgreSQL
View case study
Autonomous Support Agent end-to-end flow: a customer message is understood and planned, context gathered, an action decided against policy, permitted tools executed and the result verified — with a human approval checkpoint for consequential actions and escalation when the agent is uncertain.
Prototype · in development

Realtime Voice Agent

AI · Voice · Real-Time

A low-latency voice agent that holds natural phone conversations — booking, qualifying and answering without the robotic pauses.

Challenge
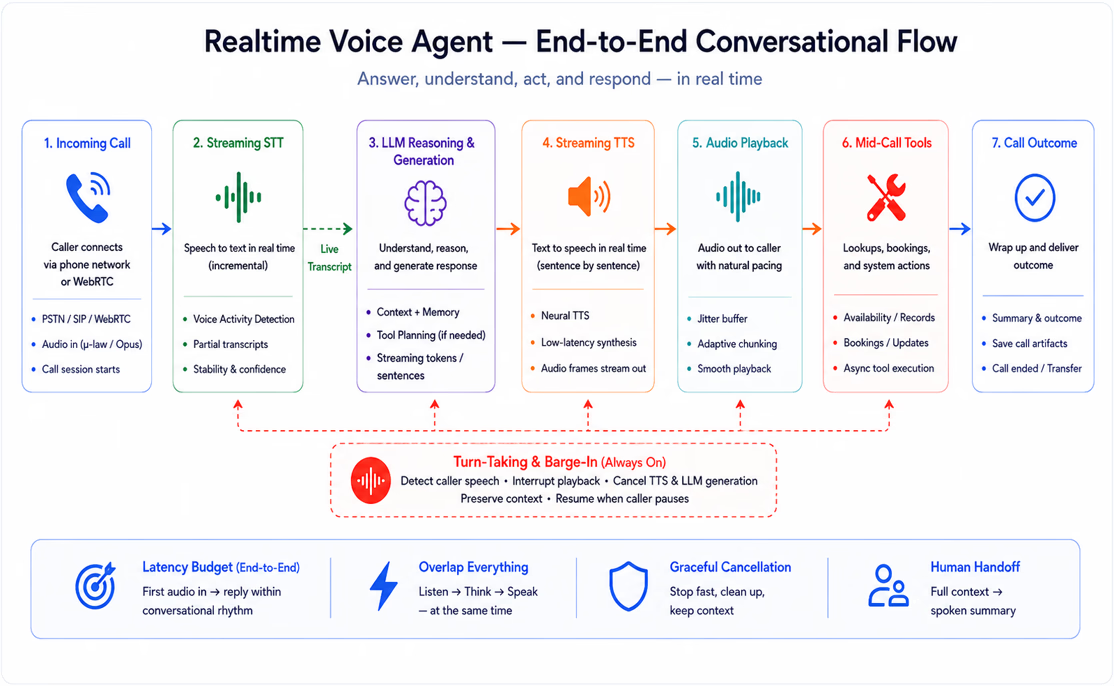
Voice AI lives or dies in the silences. Every stage — hearing, thinking, speaking — adds latency, and anything past a beat feels broken. The agent had to respond inside conversational rhythm and cope with humans interrupting it mid-sentence.
Contribution
Built the streaming voice pipeline end to end: telephony integration, streaming speech recognition, sentence-pipelined LLM and speech synthesis, barge-in handling, mid-call tool use and the latency instrumentation that made every stage accountable.
  • Python
  • Telephony / WebRTC
  • Streaming STT
  • LLM streaming
  • TTS
  • VAD
View case study
Realtime Voice Agent end-to-end conversational flow: an incoming call streams through speech recognition, LLM reasoning, speech synthesis and playback, with mid-call tools and an always-on turn-taking and barge-in controller that can interrupt any stage.

How I build with AI

Enthusiasm with an engineering spine.

01

Evals over vibes

Every AI feature ships with an evaluation suite. If quality isn't measured, it isn't real — demos lie, distributions don't.

02

Guardrails in the engine

Safety, permissions and spending limits are enforced mechanically in the execution layer — never delegated to a system prompt's good intentions.

03

Latency is the interface

Streaming, partial results and interruption handling decide whether AI feels like intelligence or like a loading spinner.

04

Humans stay in command

High-stakes actions get approval gates and audit trails. The best agents know exactly what they're not allowed to do alone.

Working surface

  • LLM product integration
  • RAG & vector search
  • AI agents & tool use
  • Diffusion & generative video pipelines
  • GPU inference orchestration
  • Local & cloud model routing
  • Realtime transcription & voice
  • Fine-tuning & LoRA workflows
  • Prompt design & evaluation
  • AI safety boundaries & moderation

Building something with AI?

Building something with AI?

From a first LLM feature to a full agentic product — I can take it from idea to production, with the guardrails and evals that make it dependable.